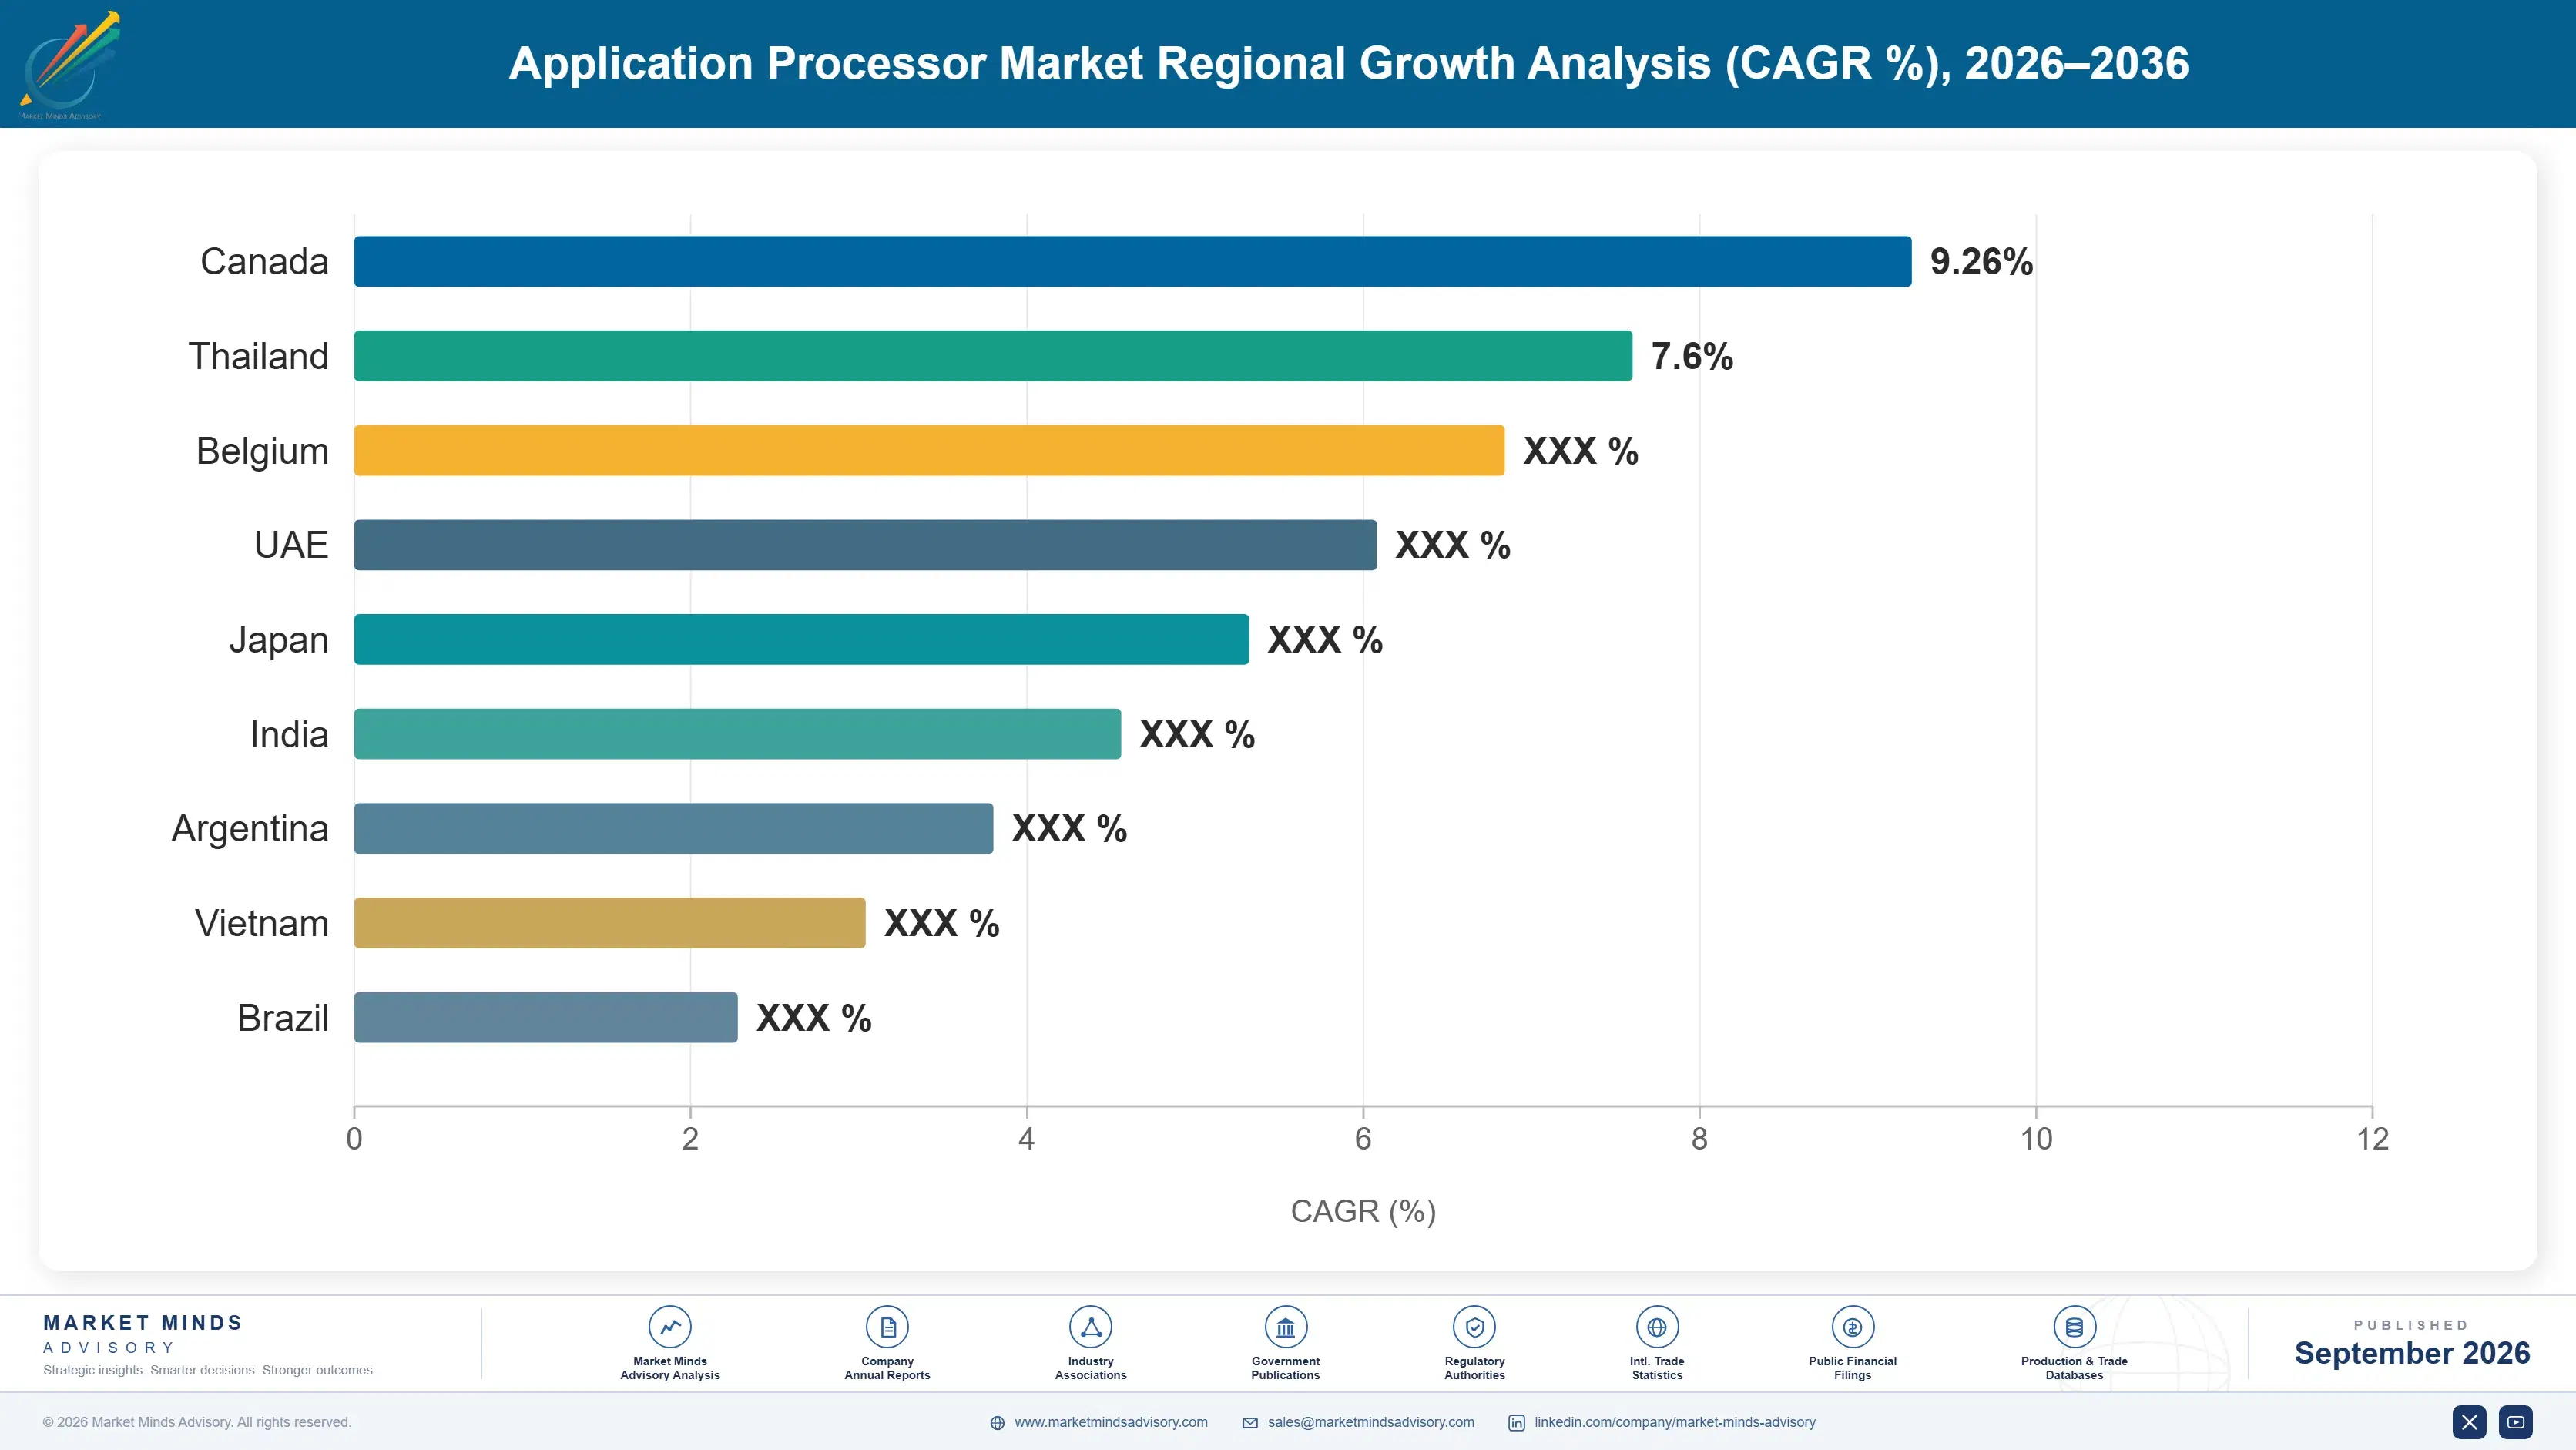
AI-Accelerated Neural Engines Steadily Displace Conventional Cores
Device makers across major East Asian and North American markets are increasingly specifying AI-accelerated application processors positioned against legacy conventional-core designs, responding to demand for on-device inference that speeds AI feature adoption without maintaining separate cloud compute dependency at scale. This shift has required chipmakers to invest in neural engine architecture and inference testing capability, a process that can take twelve to eighteen months per silicon generation given required node qualification. Device makers are increasingly treating neural capability as a competitive prerequisite for new flagship device launches, accelerating the transition considerably across the industry.
Market Impact: Adds 11 percent AI-driven volume