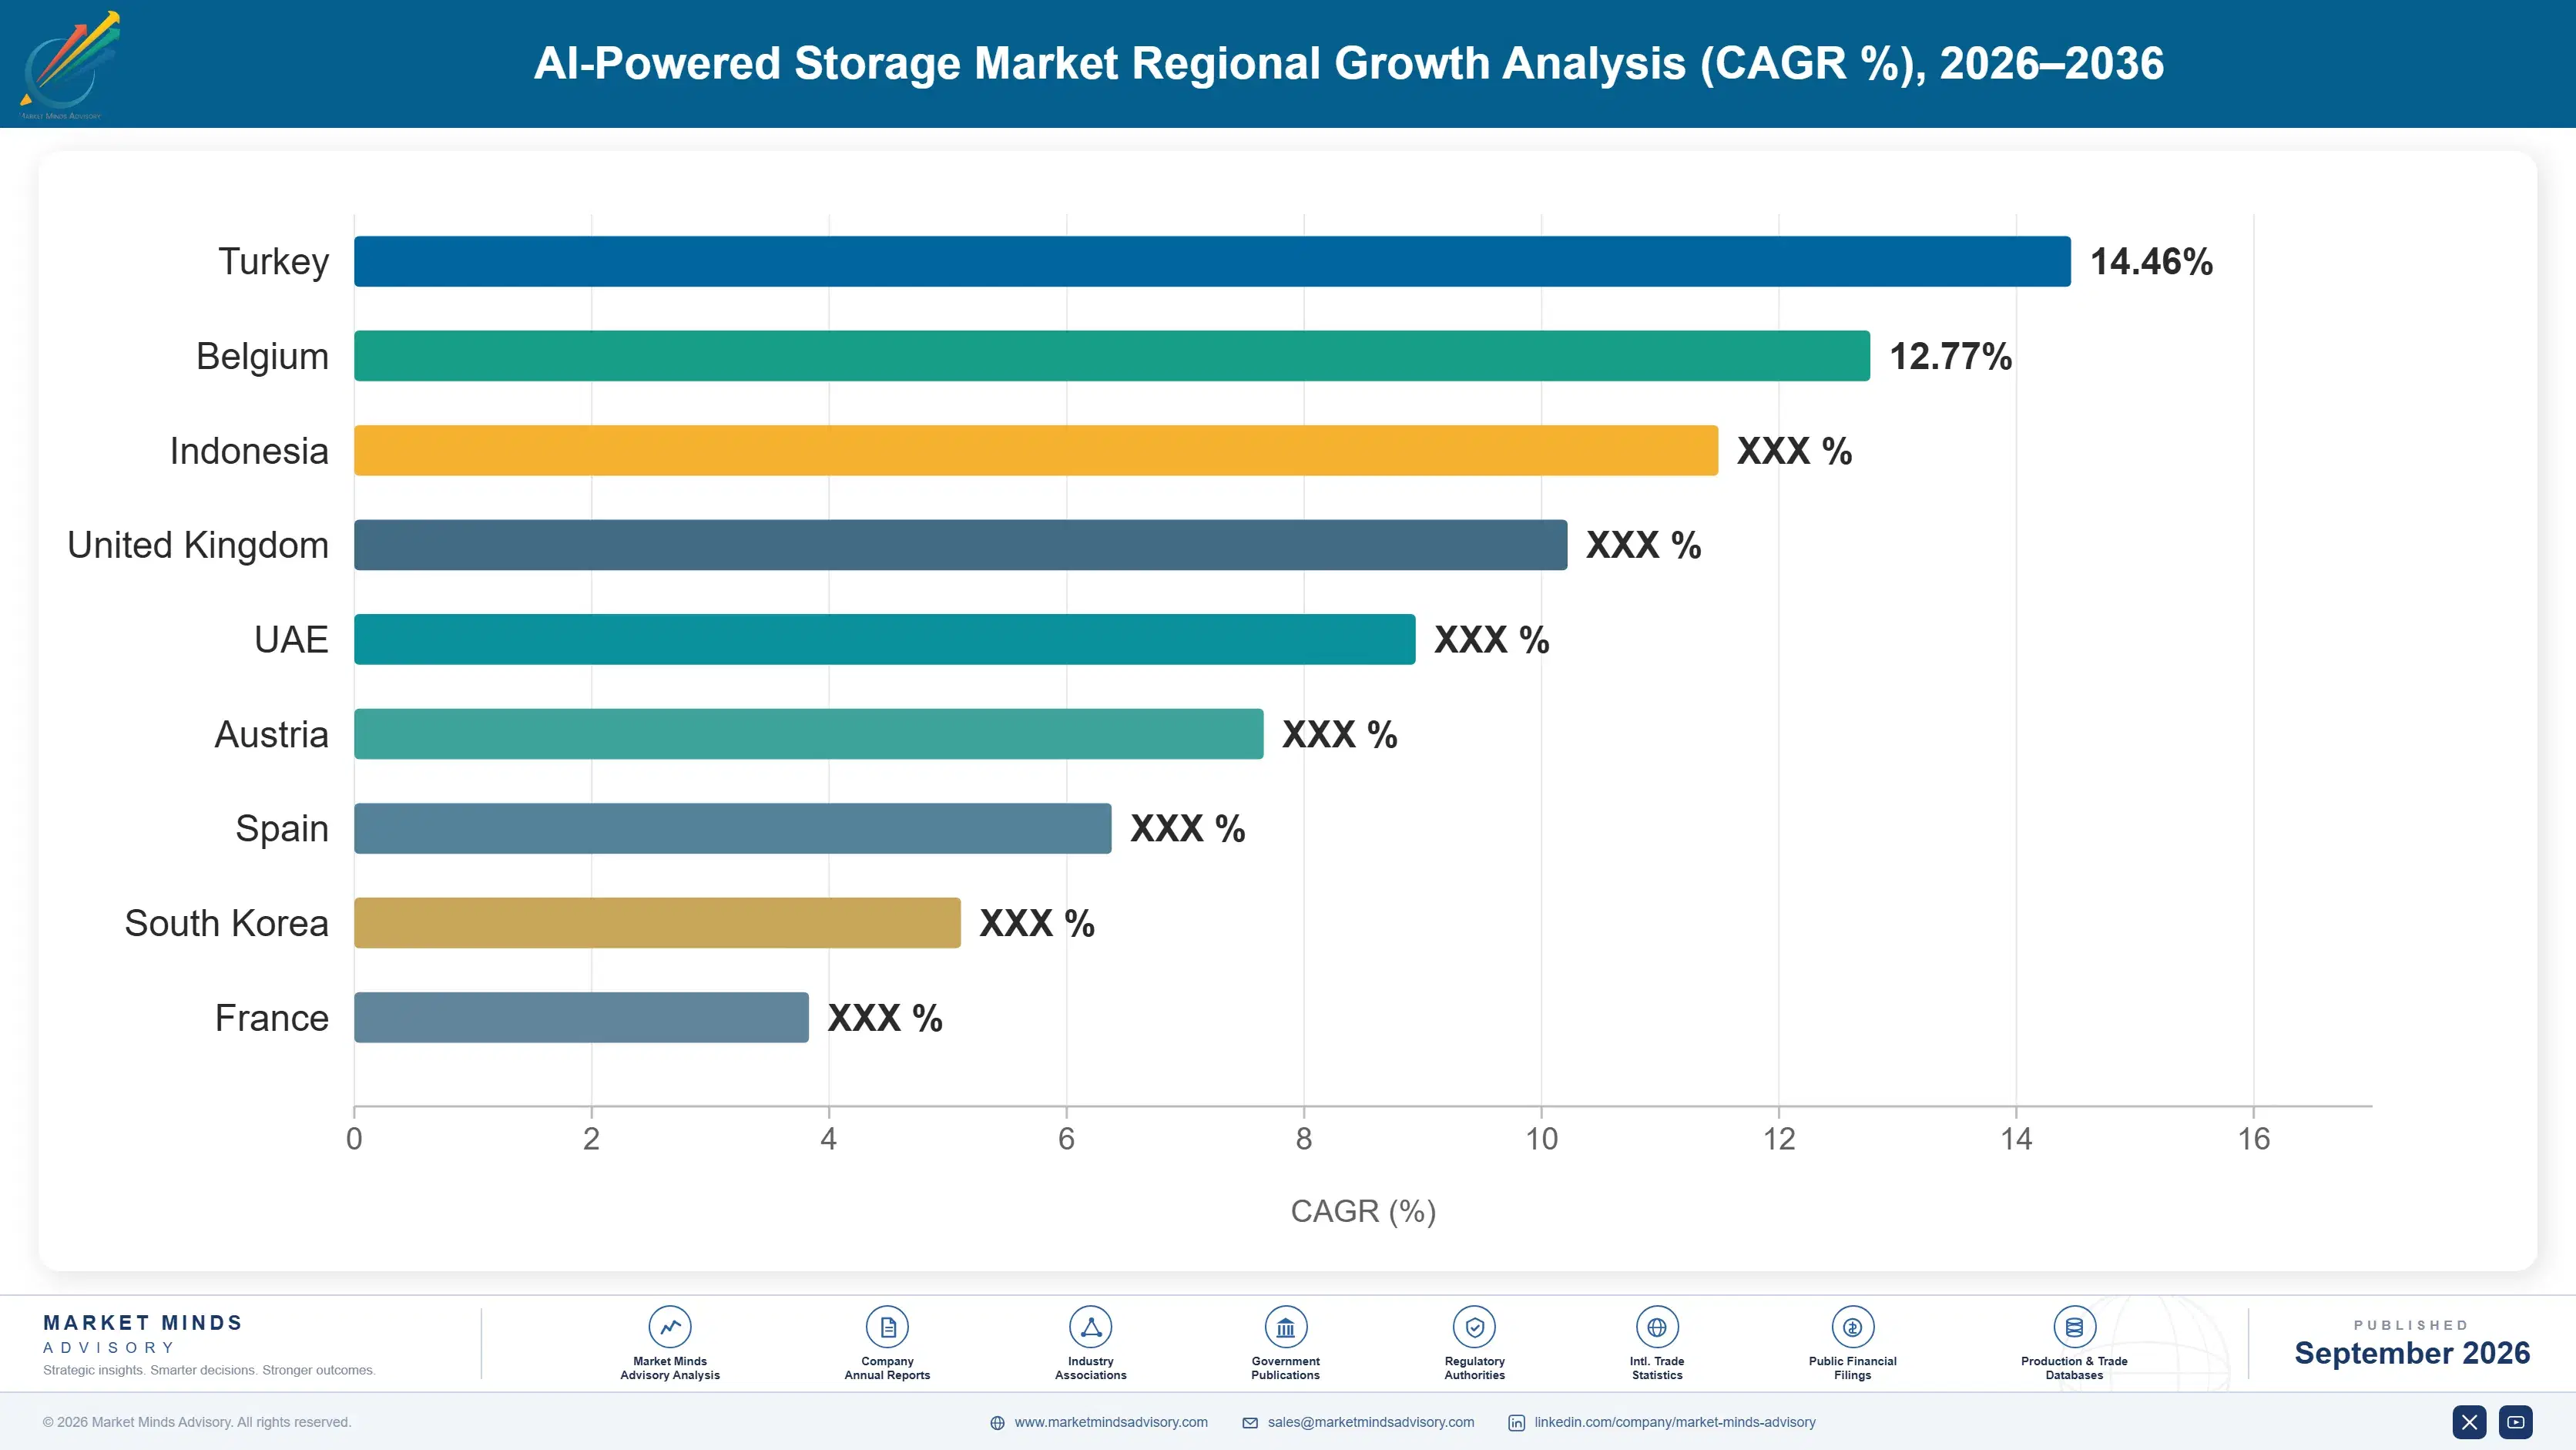
Throughput-Dense Arrays Steadily Displace Capacity-Optimized Storage
Hyperscalers across major North American and East Asian markets are increasingly specifying throughput-dense AI training storage systems positioned against legacy capacity-optimized array designs, responding to demand for sustained GPU cluster feeding that speeds training job completion without maintaining separate staging infrastructure at scale. This shift has required vendors to invest in parallel file system engineering and sustained-throughput testing capability, a process that can take six to twelve months per platform generation given required benchmark validation. Hyperscalers are increasingly treating sustained throughput capability as a competitive prerequisite for new training cluster procurement, accelerating the transition considerably across the industry.
Market Impact: Adds 9 percent AI-infrastructure-driven volume